I’m Tired, Boss
You know the meme. The weary face, the flat delivery: “I’m tired, boss.”
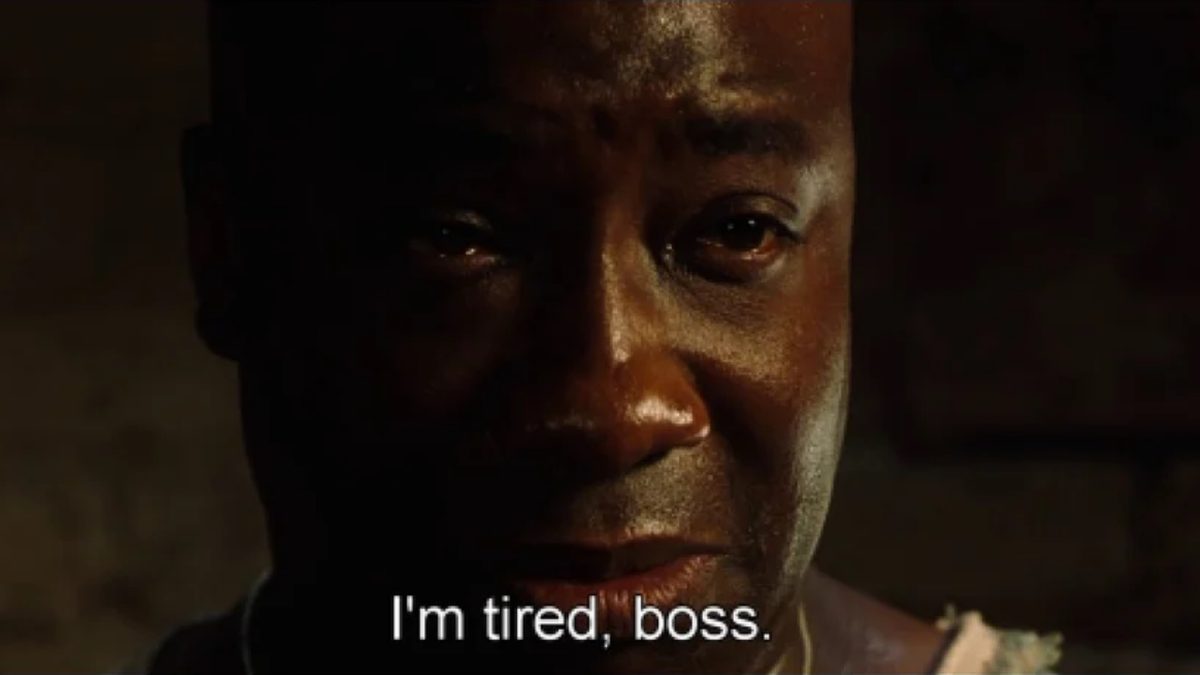
That is every patch team in 2026.
How We Got Here
This site has been tracking the climb all year:
- April: 14 Days Is No Longer Enough. AI tools started finding vulnerabilities faster than vendors could fix them.
- July: Microsoft fixed 570 CVEs in a single Patch Tuesday. Chromium added 450+ across the month.
- September: 972 CVEs. Two Windows zero-days. Six unauthenticated paths to domain compromise.
- November: Over 1,000 CVEs from Microsoft, including an exploited Outlook zero-day (CVE-2026-124194) that leaks NTLM hashes. Chrome patched its eighth exploited zero-day of 2026 the same week.
For context: in 2025, Microsoft fixed 1,130 CVEs across the whole year, roughly 94 a month. November 2025 alone was 63. November 2026 was over 1,000 in a single release.
Each month was meant to be the peak. None of them were.
The Bit Nobody Measures
We count CVEs. We count days to remediate. We rarely count the people.
- No quiet weeks. Patch Tuesday used to be an event. Now it is a baseline, with out-of-band fixes filling the gaps.
- No finish line. You close a cycle and the next one is already queued.
- Constant triage. Every release means deciding what breaks if you patch, and what breaks if you don’t.
- Same headcount. The volume has multiplied. The team has not.
Tired people make mistakes. Mistakes in patching mean missed devices, failed rollbacks and exposure windows nobody spotted.
Why It Won’t Ease Off
AI-assisted discovery does not get bored. It does not take holidays. Attackers have the same tools.
The volume is the new normal. Planning for it to drop is not a strategy.
What Actually Helps
You can’t out-work this. You can out-organise it.
- Automate Windows. Intune or WSUS should push standard updates with no human clicking through them.
- Automate Linux too. Turn on unattended-upgrades on Debian and Ubuntu, or dnf-automatic on RHEL-based systems, for security updates at minimum. Use Ansible or your RMM to patch fleets in one run.
- Plan for kernel reboots. Most Linux kernel fixes need a restart. Schedule them, or use live patching where your distribution supports it.
- Patch the stack, not just the OS. PHP, Java and Nginx sit on internet-facing servers and are prime targets. Track their versions, subscribe to their security announcements and update them on the same cadence as the OS.
- Watch what you bundled. Java apps ship their own libraries and runtimes. PHP sites pull in Composer packages. An OS update won’t fix those, so scan dependencies and rebuild.
- Don’t forget desktop apps. Browsers, PDF readers and runtimes get exploited as often as the OS. Cover them in the same process.
- Use rings. Pilot, broad, critical. Let a small group take the risk first, then move fast.
- Prioritise ruthlessly. Actively exploited and internet-facing first, within 24 to 72 hours. Everything else on a steady cadence.
- Measure coverage, not effort. Know what percentage of devices and services are patched, Windows and Linux alike. Chase the gaps, not the noise.
- Cut the estate. Unsupported software, end-of-life PHP and Java versions, old distros and forgotten devices create work forever. Remove them.
- Look after the team. Rotate the on-call. Recognise the work. Burned-out staff leave, and they take your knowledge with them.
Plan for the Patch That Breaks Things
Patching faster means more updates hit production with less testing. Sooner or later, one will break something. Plan for it now.
- Back up before you patch. Snapshot servers and VMs before major updates. Rolling back a snapshot takes minutes. Rebuilding takes days.
- Follow 3-2-1. Three copies of your data, on two types of media, one off-site. Keep at least one copy immutable or offline so ransomware can’t reach it.
- Test your restores. A backup you have never restored is a hope, not a plan. Test regularly and time it.
- Plan for machines that won’t boot. A bad update can leave devices stuck in a boot loop. Know how you will get in: BitLocker recovery keys stored somewhere you can reach when systems are down, recovery media ready, and remote console access to servers.
- Keep a rollback path. Use Intune and WSUS to pause or pull a bad update fast. On Linux, keep the previous kernel in the boot menu and pin package versions when needed.
- Write it down. A short disaster recovery plan: who decides, who does what, what gets restored first. Tired people at 2am follow checklists, not memory.
- Know your recovery times. Agree how long each key system can be down and how much data you can afford to lose. Build backups to match.
Speed and resilience go together. You can only patch fast if you know you can recover.
How We Can Help
We help organisations patch faster without burning out their teams:
- Vulnerability scanning across Windows, Linux and web stacks, so you know what is exposed and what to fix first.
- Patching process reviews to find the manual steps, gaps and bottlenecks slowing you down.
- Endpoint hardening with Intune and SCCM, cutting the attack surface before the next patch lands.
- Cyber Essentials support, so your patching meets the 14-day rule with room to spare.
Need a patching process that doesn’t rely on heroics? Get in touch.
Bottom Line
The patch grind is not a phase. It is the job now.
Build a process that survives a tired team, because you are going to have one.
Patch early. Patch often. And let your people sleep.